
Table of Contents
Table of Contents
Google changes its HTML markup often enough that scrapers built on BeautifulSoup selectors tend to break within weeks, not years, which is the real reason so many developers have quietly moved from parsing raw HTML to calling a structured Web Search API in Python instead.
None of this is difficult to build correctly. What’s difficult is doing it reliably: handling pagination, localization, device targeting, rate limits, and malformed responses without rewriting your scraper every time a search engine tweaks its layout. Building a reliable Web Search API Python application isn’t difficult; choosing an API that returns clean, structured data without maintenance overhead is what determines long-term success.
That’s the problem this guide works through, using SERPHouse’s Web Search API as the running example. You’ll see how authentication works, how to structure requests for Google Web, Lite Web, Jobs, Images, Shopping, News, and Local search, how to parse the JSON responses in Python, and how to take a single working script toward something production-ready, with retries, logging, and proper secret handling.
Before touching a single endpoint, it helps to understand what a “Web Search API” actually does under the hood, and why that mechanism is more durable than scraping a search results page directly.
What Is a Web Search API?
Picture a junior developer asked to check search rankings for fifty keywords, twice a day, across three countries. Doing that by hand (opening a browser, typing each query, screenshotting the results) doesn’t scale past a handful of terms. A Web Search API automates exactly that job: it sends the query to a real search engine, waits for the results page to render, extracts everything meaningful from it, and hands your program a clean JSON object instead of a wall of HTML.
The lifecycle looks like this:
User request: your application decides it needs search data for a query (a keyword, a product name, a company).
HTTP request: your Python script sends that query, along with parameters like location and device, to the search API endpoint.
Search engine processing: the provider issues the actual search against Google, Bing, or Yahoo, handling anything that would normally block an automated request (CAPTCHAs, IP blocks, JavaScript rendering).
SERPHouse retrieval: the raw results page is captured and parsed into a consistent internal schema.
JSON response: that schema is returned to you as structured JSON: organic results, ads, images, knowledge panels, and so on, each in predictable fields.
Python processing: your code reads specific keys out of that JSON (title, link, snippet, position) instead of hunting through <div> tags. This is the core loop that any Web Search API Python integration ends up following, regardless of which vertical you’re querying.
Structured JSON is preferable to HTML scraping for a simple reason: HTML is a presentation format, not a data format. Search engines change class names, nesting, and layout constantly, and a scraper tied to those details fails silently or loudly the moment something shifts. A JSON response from an API is a contract: the fields stay consistent even when the underlying page design doesn’t. That consistency is also why maintenance costs drop: instead of a developer periodically re-inspecting page source and patching selectors, the parsing logic on your end barely changes release to release.
That predictability is precisely why Python, more than most languages, has become the default choice for consuming these APIs.
Why Python Is the Preferred Language for Web Search APIs
“Python is easy” doesn’t explain why it dominates this particular niche. Plenty of languages are easy. The real reasons are more specific:
The requests library. Sending a POST request with a JSON body and a Bearer token header takes four lines in Python. There’s no boilerplate client setup, no verbose type scaffolding, just a function call.
Native JSON handling. Python’s json module (and requests’ built-in .json() method) turns an API response into a native dictionary immediately, with no separate deserialization step.
AI integration. Nearly every major LLM framework (LangChain, LlamaIndex, the Anthropic and OpenAI SDKs) is Python-first, which makes it the natural glue language between a search API and an AI agent.
Data pipelines. Pairing pandas with a search API response turns raw JSON into a dataframe ready for analysis or a database insert in a couple of lines.
These strengths are reflected in the projects developers build with search data. AI agents can ground answers in live web results instead of relying on potentially inaccurate information. Rank trackers can monitor keyword positions daily, while RAG pipelines retrieve fresh source documents before generating answers. News monitoring tools can track topics across outlets, and market research scripts can collect competitor pricing or ranking data on a schedule.
Pairing Python with SERPHouse makes these advantages even more practical. Authentication requires just a single header. Responses are returned in JSON, so they’re easy to process. There’s also no required vendor SDK, as the requests library is enough. That combination is what actually reduces development time for a Web Search API Python project. It’s not simply because “Python is easy” as an abstract claim. Python’s tooling fits well with an API designed for simple integration.
Why Developers Choose SERPHouse Web Search API
It’s easy to list features. It’s more useful to explain what breaks without them, and how SERPHouse addresses each break point specifically.
Authentication
Problem: Unauthenticated or loosely authenticated search endpoints are either insecure or unusably rate-limited for real applications.
How SERPHouse solves it: Every request is authenticated with a Bearer token sent in the Authorization header (SERPHouse also supports passing the key as an api_token query parameter as an alternative). An invalid or missing key returns a 401 Unauthenticated response rather than silently degraded data.
Practical example: A single header, Authorization: Bearer <YOUR_API_KEY>, is enough for every endpoint: Google Web, Jobs, Images, Shopping, News, and Local.
Real implementation scenario: A scheduled script can run nightly to refresh a rank-tracking dashboard, with the API key stored as an environment variable. The same header can then be reused across every request it sends.
Structured JSON
Problem: Parsing raw search-engine HTML means writing brittle selectors that break whenever the engine redesigns its results page.
How SERPHouse solves it: Every response, regardless of which Google vertical you’re querying, comes back as JSON with consistent, documented keys (search_metadata, search_parameters, and the results themselves).
Practical example: A Google Web search response includes a search_parameters object. It shows exactly what was searched, including the query, domain, device, and location. This lets you confirm what was actually run without guessing.
Real implementation scenario: A QA script can compare search_parameters in the response with the values that were intended to be sent. This helps catch silent parameter mismatches early. It can prevent incorrect data from entering your dataset.
Location Targeting
Problem: Search results are heavily localized. The same keyword returns different rankings and local packs depending on city, state, or country.
How SERPHouse solves it: A loc (or location) parameter lets you target results down to the city level (for example “Austin,Texas,United States”).
Practical example: Searching “restaurants” with loc set to Austin, Texas returns a fundamentally different local pack than the same query targeted at New York.
Real implementation scenario: An SEO agency running weekly rank checks for a client with multiple physical store locations can loop over a list of city strings and pull location-specific rankings for each.
Device Targeting
Problem: Mobile and desktop SERPs are structurally different: different ad placement, different local pack sizes, sometimes different organic ordering entirely.
How SERPHouse solves it: A device parameter (desktop, mobile, tablet) tells the underlying scrape engine which rendering mode to use. Practical example: The Google Web search example in this guide passes “device”: “desktop”; swapping that single value to “mobile” returns the mobile-rendered SERP for the same query. Real implementation scenario: A team benchmarking mobile search visibility separately from desktop can run the identical query twice, once per device value, and diff the two result sets.
Language Support
Problem: Running an English-language query against a search engine doesn’t guarantee English-language results in every region.
How SERPHouse solves it: A lang parameter (standard two-letter codes such as en) controls the interface/results language independently of location.
Practical example: Combining lang: “en” with loc: “United States” locks both the language and the geography of the returned SERP. Real implementation scenario: A multilingual content team can run the same keyword with lang set to en, es, and fr in turn to compare how competitor content ranks across language markets.
Live Search
Problem: Some workflows need a result right now, a chatbot answering a live question, or a one-off manual lookup, and can’t wait on a queued job.
How SERPHouse solves it: The live SERP endpoint (POST /serp/live) returns results synchronously in the same HTTP response, typically within a few seconds.
Practical example: An AI agent answering a user’s question mid-conversation calls the live endpoint and gets organic results back before formulating its reply. Real implementation scenario: A customer-facing RAG chatbot fires a live search whenever a user’s question requires current information the model wasn’t trained on.
Scheduled Search
Problem: Rank tracking and monitoring workloads don’t need synchronous responses; they need the same query run reliably, repeatedly, without you manually triggering it.
How SERPHouse solves it: SERPHouse exposes scheduled search endpoints so a query can be queued to run automatically and its results retrieved later via a status/result check.
Practical example: A batch of five hundred tracked keywords can be scheduled once and checked the next morning instead of looped through synchronously. Real implementation scenario: A rank-tracking SaaS product schedules its entire keyword list nightly and pulls completed results into its database each morning without holding open connections all night.
Top 100 Results
Problem: Most search APIs cap results at the first page (roughly ten results), which is useless for competitive analysis beyond the top of the SERP.
How SERPHouse solves it: The SERP API returns up to the top 100 results for a keyword on the selected search engine and location.
Practical example: A competitor-tracking script can check whether a domain appears anywhere in positions 1 through 100, not just the first page. Real implementation scenario: An SEO team investigating a ranking drop can see whether a page slipped from position 4 to position 47 rather than just disappearing from a ten-result window.
Multiple Search Engines
Problem: A tool built only against Google misses market share in regions or industries where Bing or Yahoo matter.
How SERPHouse solves it: The SERP API documents support for Google, Bing, and Yahoo through the same general request pattern.
Practical example: The same style of authenticated POST request that targets Google’s SERP can be pointed at Bing’s equivalent endpoint for a side-by-side comparison. Real implementation scenario: A market research report comparing visibility across search engines pulls the same keyword set from each engine and merges the results into one dataset.
Taken together, these capabilities solve a consistent underlying problem: search data is inherently messy, localized, and fragile to collect by hand, and SERPHouse’s job is to absorb that fragility so your Python code only has to deal with clean JSON.
Prerequisites Before Writing Code
Before writing your first request, get four things in order.
Python version. Use Python 3.8 or newer. Anything older has inconsistent requests/json behavior and is past its useful support window; most current libraries assume 3.8+ syntax and type hints.
Installing requests. SERPHouse’s API is a standard REST API, so the only real dependency for a Web Search API Python setup is:
No official SDK is required; every example in this guide runs on requests alone, which keeps the dependency footprint small and avoids being locked into a wrapper library that lags behind the API itself.
Virtual environment. Create one before installing anything:
This exists so your project’s dependencies don’t collide with system-wide packages or other projects’ pinned versions, a common source of “it works on my machine” bugs.
API key. Sign up at SERPHouse and confirm your email; the key appears on your account dashboard afterward. This key is what authorizes every request and is tied to your subscription’s usage.
Bearer authentication. Every request needs an Authorization: Bearer <YOUR_API_KEY> header. There’s nothing more exotic than that: no OAuth handshake, no token refresh cycle.
Common beginner mistakes at this stage: forgetting to activate the virtual environment before running pip install, pasting the API key with extra whitespace or quotation marks into the header string, and testing requests without checking response.status_code first, which hides authentication or validation errors behind a confusing empty result instead of a clear error message.
Authentication Explained
Bearer authentication works by putting your API key directly in the request’s Authorization header, prefixed with the word Bearer:
Authorization: Bearer <YOUR_API_KEY>
The server reads that header on every incoming request and checks the token against your account before doing anything else: no session cookies, no separate login step. SERPHouse also supports passing the key as an api_token query-string parameter as an alternative to the header, though the header approach is the more common pattern in the examples throughout this guide.
If credentials are missing or invalid, the API returns a 401 Unauthorized (“Unauthenticated”) response instead of processing the search. That’s a deliberate fail-closed behavior: a bad key never silently returns partial or cached data, it simply refuses the request outright, which makes authentication bugs easy to catch in testing rather than something that surfaces as mysteriously empty results in production.
A few security practices are worth treating as non-negotiable:
Use environment variables. Read the key with os.environ.get(“SERPHOUSE_API_KEY”) instead of typing it into your script.
Use .env files locally, loaded with a library like python-dotenv, and add that file to .gitignore so it never reaches version control.
Use a secret manager in production: AWS Secrets Manager, HashiCorp Vault, or your cloud provider’s equivalent, rather than environment variables baked into a deployment image.
Never hardcode production API keys directly into source files, notebooks, or anything that might get committed, screenshotted, or pasted into a chat log.
The key itself is directly tied to your subscription usage, so a leaked key isn’t just a security problem; it’s a billing problem too.
Python Code Examples
Each example below follows the same request pattern common to any Web Search API Python integration: a JSON payload wrapped in a data object, sent via requests.post() with a Bearer token header. What changes between them is the endpoint and the fields relevant to that vertical.
Example 1: Google Web Search
Problem this example solves: Most applications need a general-purpose keyword search, the same kind of query you’d type into google.com, returned as structured data instead of a rendered page.
When you should use it: Rank tracking, general SEO monitoring, competitive research, or as the default search tool behind an AI agent that needs grounded web results.
Key takeaways: This is the template every other example in this guide builds on: same headers, same POST pattern, same data wrapper; only the endpoint and payload fields change.
Example 2: Google Lite Web Search
Problem this example solves: A full SERP payload (ads, knowledge panels, people-also-ask, images) is often more data than a lightweight application needs, and it costs more to process and store.
When you should use it: Simple lookups where only core organic results matter, a chatbot doing a quick fact check, or a low-overhead search widget.
Key takeaways: Use the lite endpoint when you want lower response overhead and don’t need the extended SERP feature set.
Example 3: Google Jobs API
Problem this example solves: Job listing data is scattered across many sites, and manually checking Google’s jobs results for a given role and location doesn’t scale.
When you should use it: Recruiting tools, labor-market research, or products that aggregate open roles by title and location.
Key takeaways: The Jobs endpoint follows the exact same authentication and payload shape as the general web search. Once you understand one endpoint, the rest are variations on the same pattern.
Example 4: Google Images API
Problem this example solves: Visual content research, checking how a brand’s imagery ranks, or sourcing reference images for a design or content pipeline, requires structured access to Google Images rather than manually scrolling through a browser.
When you should use it: Building icon/asset research tools, monitoring how a brand’s product imagery ranks, or feeding image URLs into a downstream computer-vision pipeline.
Key takeaways: Image search follows the same authenticated JSON pattern, with page as the main addition worth understanding for anything beyond a single results screen.
Example 5: Google Shopping API
Problem this example solves: Price monitoring and product-availability tracking across e-commerce listings is tedious to do manually and changes daily.
When you should use it: Competitor price tracking, market intelligence dashboards, or an e-commerce tool that needs to show “prices elsewhere” for a given product.
Key takeaways: Shopping search reuses the same request shape as every other endpoint in this guide. The differentiator is purely the query intent and how you plan to use the returned pricing data.
Example 6: Google News API
Problem this example solves: Tracking how a topic, company, or public figure is being covered across news outlets in near real time is impractical to do by manually refreshing search results.
When you should use it: Brand monitoring, PR tracking, or a news-aggregation feature inside a larger product.
Key takeaways: News search benefits the most from combining this pattern with a scheduler (see Section 4’s discussion of scheduled search), since news relevance decays quickly.
Example 7: Google Local API
Problem this example solves: Local business visibility, where a business ranks in the “local pack” for a given category and city, is one of the most requested and hardest-to-scrape pieces of SEO data.
When you should use it: Local SEO tools, multi-location business dashboards, or competitive analysis for brick-and-mortar businesses.
Key takeaways: Local search closes out this set of examples by reinforcing the core lesson of this section: once you understand the authentication and payload-wrapping pattern, adapting to a new SERPHouse endpoint is mostly a matter of changing the URL and the query-specific fields.
Understanding Search Parameters
Parameters aren’t just fields to fill in. Each one changes what data comes back and how it’s shaped, and getting them right is a core part of building a dependable Web Search API Python workflow. Grouped by purpose:
Query q: the actual search term or phrase.
Localization domain: selects which regional search-engine domain to query (e.g. google.com). lang: controls the results/interface language. loc: targets results to a specific geography, from country down to city level.
Device device: controls which rendering mode (desktop, mobile, tablet) the search is run in.
Pagination page: moves through additional pages of results beyond the first batch.
Filters Not every endpoint documents additional filter parameters beyond query, localization, device, and pagination in the examples shown here. Avoid inventing filter fields that aren’t part of the documented payload for a given endpoint, since undocumented fields are typically ignored or, worse, silently misinterpreted.
Output responseType: on endpoints where it’s documented (such as the Jobs API), controls whether the response comes back as json or html.
Understanding the JSON Response
SERPHouse’s live search responses generally follow a consistent shape, built around two top-level sections plus the actual results, and understanding that shape is the last piece needed to wire up a complete Web Search API Python client.
search_metadata carries information about the request itself: an internal id for the job, a status field (success or error), and timestamps like created_at and processed_at. This is the section you check first to confirm the request actually completed.
search_parameters echoes back exactly what was searched: domain, lang, country, location, q, device, and the constructed underlying search URL. This is worth logging alongside your results, since it lets you audit later whether a given result set was actually generated with the parameters you intended.
The results themselves, organic listings, jobs, images, shopping items, news articles, or local businesses depending on the endpoint, sit in their own section of the response, typically as a list of objects with fields like position, title, link, and snippet (organic), or endpoint-specific fields like price (shopping) or rating (local).
In Python, accessing these fields is a matter of walking the parsed dictionary:
For most applications, the fields worth persisting to a database are the query itself, the timestamp, and whichever result-level fields matter to your use case: position and link for rank tracking, price for shopping monitoring, rating and address for local business tracking. Storing the full raw JSON alongside the extracted fields is a reasonable habit early on, since it lets you re-parse historical data if your extraction logic changes later without re-querying the API.
Practical Applications
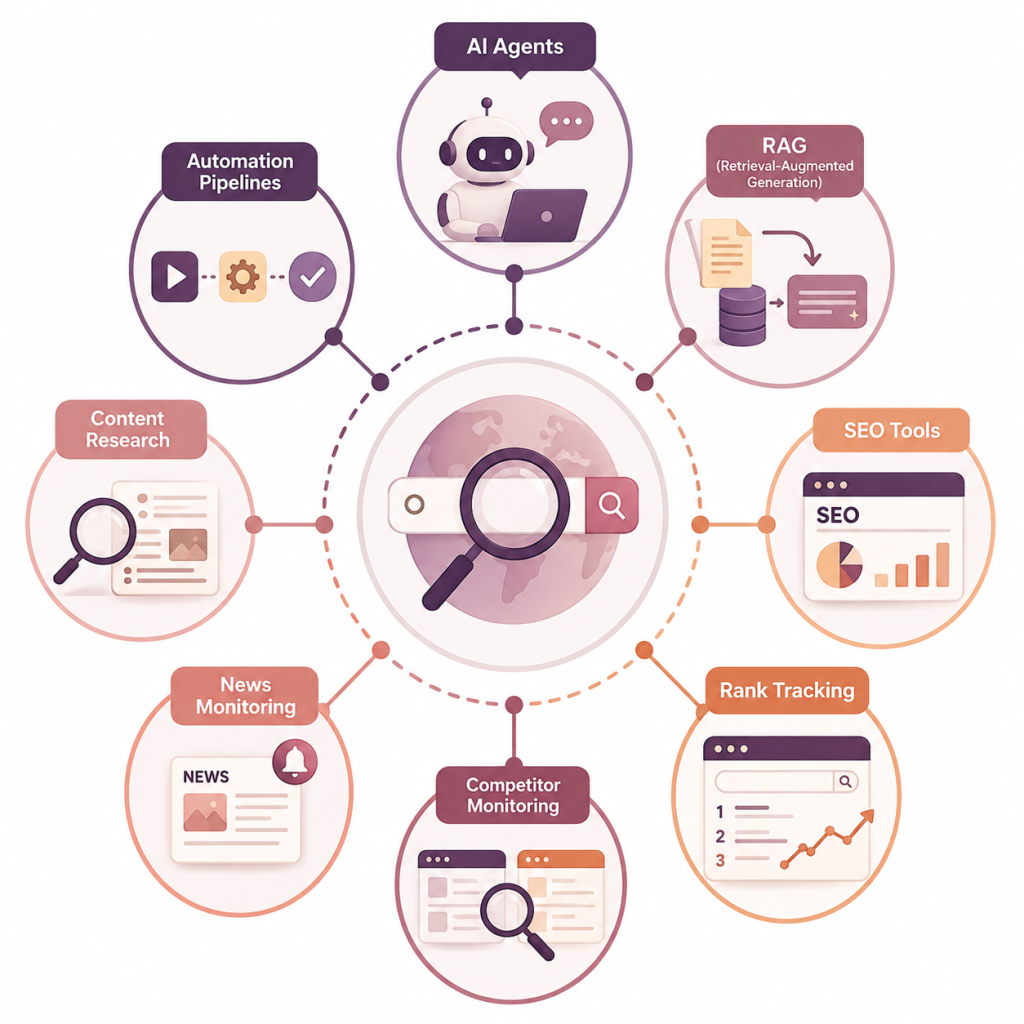
AI Agents
The problem: language models answer from a frozen training snapshot, which means anything recent or fast-changing gets guessed at rather than known. Developers solve this by giving the agent a search tool it can call mid-conversation, often built as a Web Search API Python client the agent invokes as a tool. Search data matters here because it’s the only way to ground an answer in the present moment. SERPHouse fits into this workflow as the retrieval step that runs before the model formulates its final response; the live search endpoint returns fast enough to sit inside a single conversational turn.
RAG (Retrieval-Augmented Generation)
The problem: RAG systems built purely on a static document store go stale the moment the world changes and the store doesn’t. Developers solve this by adding live web search as a supplementary retrieval source alongside internal documents. Search data matters because it closes the gap between “what we indexed last month” and “what’s true right now.” SERPHouse fits in as an on-demand retrieval call the RAG pipeline triggers when internal sources are insufficient or outdated.
SEO Tools
The problem: manually checking how a site ranks across dozens of keywords and locations doesn’t scale past a handful of pages. Developers solve this with automated polling scripts. Search data matters because rankings are the actual product SEO work is trying to move. SERPHouse fits in as the data source behind the dashboard, with the Top 100 results capability meaning a tool isn’t blind past position ten.
Rank Tracking
The problem: rankings fluctuate daily, and without historical data you can’t tell whether a drop is a blip or a trend. Developers solve this by scheduling repeated searches and storing position over time. Search data matters because a single snapshot tells you almost nothing on its own. SERPHouse fits in through its scheduled search capability, which is built specifically for this repeated-polling pattern rather than one-off live lookups.
Competitor Monitoring
The problem: knowing what a competitor is doing (pricing, ad copy, ranking position) usually means someone manually checking their listings periodically. Developers solve this by automating the same checks a human would do by hand. Search data matters because competitive positioning is directly visible in SERP data. SERPHouse returns the same structured fields, including price, position, and listing content. The format stays consistent across competitors and keywords. This allows one script to scale across an entire competitor list.
News Monitoring
The problem: coverage of a company, person, or event can appear across dozens of outlets within hours, and manual monitoring misses most of it. Developers solve this with scheduled polling against the News endpoint. Search data matters because timeliness is the entire value of a news-monitoring feature. SERPHouse fits in by returning structured article data, headline, source, and timestamp that a monitoring dashboard can display or alert on directly.
Content Research
The problem: writers and content strategists need to know what’s already ranking for a topic before producing new material, or they risk duplicating existing coverage. Developers solve this by pulling top-ranking organic and related results before drafting. Search data matters because it shows the actual competitive landscape for a topic, not a guess at it. SERPHouse fits in as the first research step in a content pipeline, feeding titles and snippets into an outline-generation step.
Automation Pipelines
The problem: any of the above becomes tedious and error-prone if run manually on a recurring basis. A Web Search API Python script is easy to hand off to a scheduler once it works reliably on its own. Developers solve this by wrapping search calls in scheduled jobs (cron, Airflow, cloud schedulers) that run without manual triggering. Search data matters because automation depends on a stable and structured data source. That’s the main reason to choose an API over scraping in the first place. SERPHouse fits in as a dependable node in that pipeline, since its JSON contract doesn’t shift the way scraped HTML does.
Error Handling & Debugging
Graceful error handling separates a demo script from a production-ready Web Search API Python integration. Each status code should be handled as a distinct case. Treating every error as a generic failure can make troubleshooting much harder.
400: Bad Request/validation error
This happens when the request body fails validation, a missing required field like q, or a malformed JSON payload. You’ll typically see field-specific error messages in the response body identifying exactly which field failed. Recovery is usually immediate: fix the payload and resend. Log the full response body on a 400, not just the status code, since the validation detail is what tells you what to fix.
401: Unauthenticated
The API key is missing, malformed, or invalid. Identify it by checking whether the Authorization header is present and correctly formatted (Bearer <key>, no extra whitespace). Recovery starts by checking whether your environment variable or Secret Manager is actually populated at runtime. A common cause is a .env file that loads locally but isn’t loaded the same way in production.
402: Payment Required
Your account has run out of credits, or there’s a billing problem. This isn’t a code bug, it’s an account-state issue. Recovery means checking your plan/usage dashboard rather than retrying the request, since retrying won’t help until credits or billing are resolved.
404: Not Found
Typically surfaces on status/result-check endpoints when an invalid ID is provided (for example, checking the status of a SERP job with a nonexistent ID). Recovery means verifying the ID was captured correctly from the original request’s response before using it in a follow-up call.
405: Method Not Allowed
The wrong HTTP method was used for an endpoint (a GET where a POST is expected, for instance). Recovery is simply matching the documented method for that specific endpoint.
500: Internal Error
A server-side failure unrelated to your request. Recovery here is where retry logic actually matters, a short backoff-and-retry is reasonable, since these are typically transient.
Performance & Production Best Practices
Environment variables
Keep the API key and any environment-specific base URLs out of source code entirely. This matters as much for accidental leaks (a key committed to a public repo) as for simple deployment flexibility between staging and production.
Caching
For queries that don’t need fresh data every time, caching can reduce unnecessary requests. For example, competitor product listings that rarely change can be cached for a reasonable period instead of being queried repeatedly. This reduces both latency and API usage.
Logging
Structured logging of request parameters, response status, and elapsed time turns production incidents into quick lookups instead of guesswork. It also helps identify patterns, such as a specific location string consistently triggering validation errors.
Monitoring
Track error rates and response latency over time, not just at the moment something breaks. A slow but not-yet-failing endpoint is often the first sign of a problem worth investigating before it becomes an outage.
API key rotation
Treat your API key like any other production secret by rotating it periodically or immediately if you suspect exposure. Make sure your deployment process allows you to replace the key without changing the code.
Conclusion
The seven examples in this guide cover Google Web, Lite Web, Jobs, Images, Shopping, News, and Local search. Despite their differences, they follow the same basic pattern. Authenticate with a Bearer token and send a JSON payload wrapped in a data object. The API then returns a predictable JSON response that you can parse and use. Once that pattern becomes familiar, you can extend it to a new endpoint or scheduled batch job. Building a production-grade Web Search API Python wrapper class then becomes a matter of repetition rather than learning new concepts.
The best next step is to run these examples with your own API key. Try different queries and locations to see how the results change. Then, build the parsing and storage logic your project requires. When questions come up about a parameter or endpoint not covered here, SERPHouse’s own documentation is the place to check next.
FAQ
Do I need an official SDK to use SERPHouse from Python for a Web Search API Python project?
No. Every endpoint is a standard REST API that accepts and returns JSON, so Python’s built-in requests library is sufficient for any integration. SERPHouse provides official SDKs for languages such as PHP and Node.js. A Python-specific SDK is not required to work with the API. You can build a thin wrapper class around requests instead. This gives you full control without adding another dependency to maintain.
How does location targeting actually work?
You pass a loc value ranging from a broad string like “US” down to a specific city, state, and country combination like “Austin, Texas,United States”. More specific location strings return more geographically precise results, which matters most for local-pack-heavy queries like restaurants or service businesses.
How do I avoid hitting rate limits?
Rate limits depend on your plan, so pace requests accordingly. For large batches, small delays or a request queue can help prevent request bursts.
Should I store the raw JSON response or just the fields I need?
Storing both is a reasonable default early on. Extract the specific fields your application needs for querying and display. Keep the raw response stored temporarily for future reference. This lets you re-parse historical data if your extraction logic changes without calling the API again.
Do I need a proxy or headless browser setup on my end to use this API?
No, that’s the entire point of using a Web Search API instead of scraping directly. Proxy rotation, CAPTCHA handling, and page rendering are managed on the provider’s side. Your Python code only needs to send a JSON request and receive a JSON response.
ai search api google search api google search api python google search integration google search results api google serp api python api integration python search api Python web scraping python web search real time web search api search api for developers search engine API web search api web search api python