
Table of Contents
Table of Contents
A recruitment platform wants to show current openings across thousands of employers and dozens of cities. The first prototype works. Then the problems compound. The same vacancy shows up three times because the employer, a job board, and a staffing agency all posted it. Listings that closed last week are still live on your site. And the folder of scrapers, one per job board, breaks every time a site changes its markup.
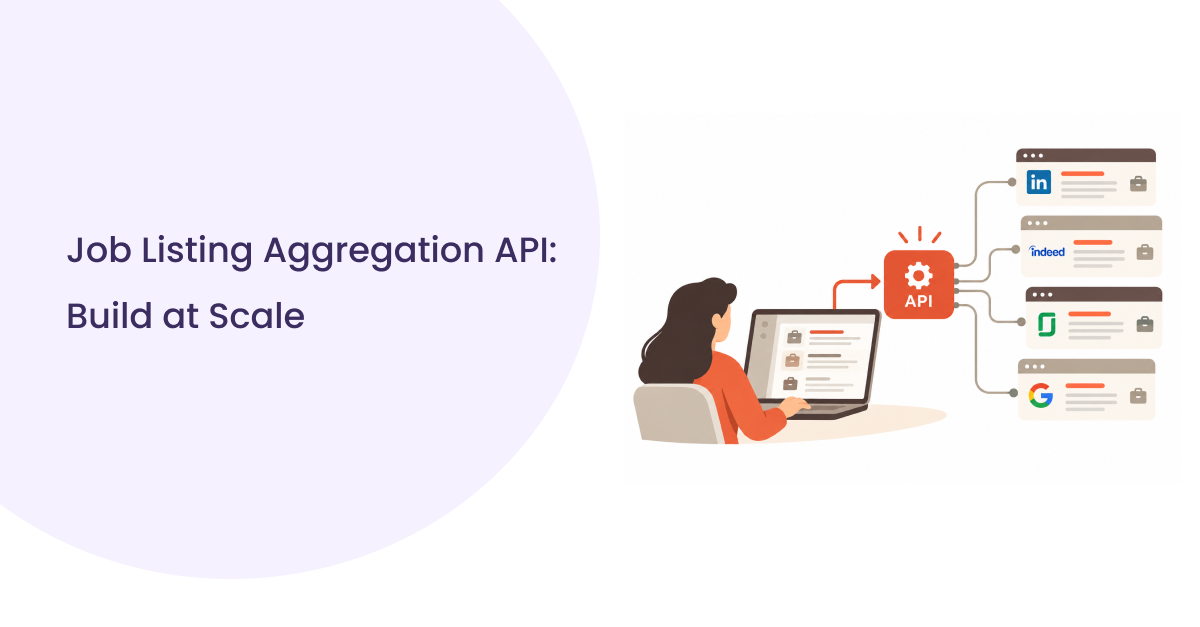
This guide is for teams evaluating a job listing aggregation API approach, specifically using search engine job results as a discovery layer. It doesn’t cover what a Google Jobs API is (we cover that in our Google Jobs API explainer). It covers what you build around it: a query inventory, a rate-aware collection layer, normalization, layered deduplication, a lifecycle that doesn’t delete live jobs by mistake, and a searchable index. Along the way, it’s explicit about which parts a search API handles and which parts your platform owns.
You’ll finish with a reference Python example and a monitoring checklist.
Why Scraping Individual Job Boards Doesn’t Scale
Most aggregators start with source-specific extraction, and most hit a wall. Every source has its own format. Sites change layouts without notice. Many use anti-automation controls, and their terms of service may restrict automated access. Each new source adds a parser to maintain, a failure mode to monitor, and another schema to map.
The data problems are worse than the engineering problems. Each board has its own job ID, so the same vacancy can have different identifiers. Location strings vary (“NYC”, “New York, NY”, “Manhattan”). Salary is annual on one site and hourly on another. Search behaviour also depends on location, so a scraper running from one region can see different results from another.
There are three broad approaches that production platforms often combine:
| Approach | Main Advantage | Main Limitation | Suitable Use Case |
| Authorized feeds and direct integrations (ATS feeds, partner APIs, XML feeds from employers) | Structured, permissioned, usually includes IDs and close dates | Limited reach; each integration has a setup cost | Primary inventory from known employers and partners |
| Source-specific extraction | Targeted coverage | High maintenance, access restrictions, terms-of-service risk | Narrow source coverage where access is permitted |
| SERP API (search engine results API) | One structured interface for job results that a search engine has already gathered, with location and language controls | Coverage depends on what the search engine shows for your queries; fields are less complete | Discovery, coverage-gap detection, and freshness signals alongside other sources |
A search-results API doesn’t replace every source. It reduces the number of scrapers you maintain for discovery and gives you an independent signal about which jobs are visible. Once you’ve chosen your collection pipeline, the next thing to get right is bulk query design.
Bulk Query Architecture for Job Aggregation
Moving from one API call to a repeatable aggregation run takes six stages. SERPHouse handles the search-results retrieval. Everything else is application-side.
Query inventory
|
v
Scheduler and workers
(Rate limits, retry policy, dead-letter queue)
|
v
SERPHouse Google Jobs API
(Provider boundary)
|
v
Validation + raw response store
|
v
Normalization → Deduplication/status
|
v
Primary database → Search index
|
v
Monitoring/metrics
Step 1. Define the Query Inventory
Your query list is your coverage strategy. A search API returns a limited set of results per query. SERPHouse’s documented Jobs response shows ten listings per query and doesn’t do the discovery work for you. A broad query like “jobs in the US” will surface a tiny slice of the market. Coverage comes from many specific queries.
Build the inventory as a combination of job role (and its common title variants), location (city, metro, or “remote”), and optionally seniority, industry, or employment type.
| Job Role | Location | Search Query |
| Software Engineer | New York | software engineer jobs New York |
| Data Analyst | Austin | data analyst jobs Austin |
| Product Manager | London | product manager jobs London |
| UX Designer | Remote | remote UX designer jobs |
Store each row with a stable location value from the locations list, language, and a priority tier. Review the inventory using data: queries that only ever return limited candidates can move to a lower frequency, while roles your users search for but your index lacks are candidates to add. The inventory drives discovery. It never guarantees full market coverage.
Step 2. Organize Queries into Batches
A batch is one scheduled pass over a slice of the inventory. Partition by priority and region so a slow query doesn’t stall the rest, and give each run an ID so a rerun skips queries that already succeeded. That makes processing idempotent.
The Google Jobs API is a real-time endpoint: each POST returns results in the response. SERPHouse’s synchronous endpoint should be treated as a request-and-response workflow. Batch SERP workflows, where supported for other result types, may schedule tasks and then deliver results through a postback or allow polling by task ID. Check the documentation for the supported result types and delivery methods. Job query scheduling and orchestration live in your application.
Workers pull queries and pace requests to your plan’s rate limit. The documentation lists 60 requests per minute for Basic and Regular plans, with custom limits on custom plans.
Concurrency controls belong in the client. A token bucket or a fixed minimum interval between calls helps avoid triggering 429 responses. Retries must be bounded: retry 429 responses, 5xx errors, and timeouts, along with documented transient errors. Don’t retry 400, 401, or 402 responses indefinitely, because those won’t fix themselves. After the last attempt, move the query to a dead-letter list for review.
Step 3. Retrieve and Validate Results
Treat every response as two checks: the HTTP status and the body’s status field. Then confirm that the expected path, results.results.jobs, exists.
An empty jobs array can be a valid result, not an error, but log it per query because a sudden spike in empty results across many queries usually signals a problem with the inventory or collection process.
Validate each listing minimally. If a title or employer can’t be matched or displayed, reject it and count it. Store the raw response body keyed by run ID and query. When your normalizer changes next month, you can reprocess history without paying to collect it again.
Step 4. Normalize the Listings
Normalization maps search results into your internal schema. With SERPHouse’s Jobs response, title, company_name, and location map directly, but they still need cleaning.
Decode HTML entities such as & and normalize multi-site locations such as “Erlangen (+ 5 more locations).” Employment type, relative posting age, and salary strings may appear in the extensions array, in the request language, and many listings don’t include salary at all. Parse what’s there and never infer a salary or employment type you didn’t see.
Step 5. Deduplicate and Merge Records
Each normalized record gets matched against existing records before it’s written. Deduplication is covered in its own section below.
Step 6. Update the Searchable Index
Upsert into the primary database first, then propagate changes to the search index. New records get a new last_seen timestamp, and records whose status changes (for example, to possibly_stale) are updated in both places so the database and index agree.
Deduplication and Refresh Scheduling
Why Duplicate Job Listings Occur
Duplicates are the default state of job data. An employer posts on its careers site and several boards publish the same opening under their own names. Boards syndicate to each other, so one vacancy surfaces under many URLs. A multi-location role appears once per city, or once with “+5 locations.”
An employer can close and repost a job to bump its visibility. Two genuinely different openings (“Data Analyst, Marketing” and “Data Analyst, Finance” at the same company) can look almost identical. A deduplication system over-merges the last case and under-merges the first.
Lightcast, which publishes its job-postings methodology, reports that duplicates can account for a substantial share of the postings it collects. The exact rate depends on the sources and collection method, so measure duplication in your own data.
How Do You Avoid Duplicates?
Use layered matching: exact identifiers, then canonical URLs, then normalized composite keys, then similarity scoring for the remaining near-misses. Keep evidence of every merge. Each layer catches what the previous one missed, and the strict layers run first so the fuzzy ones have less work to do.
Layer 1: Exact identifier
Use a source-specific job ID when one exists. Feeds and ATS integrations usually provide one. In SERPHouse’s Jobs response, there is no documented job ID. The share_link URL may carry an htidocid parameter that can serve as a hint, but treat it as undocumented: match on it when it’s present, and never use it as the only key.
Layer 2: Canonical URL
Remove tracking parameters such as utm_*, normalize the host, and remove trailing slashes before comparing URLs. Be careful with apply links from aggregated results: one listing’s apply options may include links to the same employer’s postings in other cities and for other roles. Use apply links as supporting evidence, not as the sole identity.
Layer 3: Composite-key matching
Use employer + title + city. This catches many cross-source duplicates. It creates false negatives when titles are worded differently and false positives when an employer has two openings with the same title in one city. Adding employment type to the key, where available, can reduce risk.
Layer 4: Similarity matching
When records have a normalized employer and location but no key match, compare titles using token-set similarity and compare description snippets where available. Automatically merge high-confidence matches, send a middle band to a review queue, and keep records separate below the threshold. Tune thresholds against a hand-labelled sample from your own data rather than using a universal number.
Layer 5: Merge and preserve provenance
Keep one canonical record per duplicate group. Prefer the employer’s own source for the title and description, keep the earliest first_seen timestamp, and store every source URL with its own last_seen time. Never discard a field because the “winning” source lacks it.
Illustrative Deduplication Example
The following records illustrate how the same vacancy can appear across different sources.
| Field | Record A | Record B | Record C |
| Source | Acme Health Careers | BrightPath Staffing | |
| Employer | Acme Health Inc. | Acme Health | BrightPath Staffing (client: Acme Health) |
| Title | Senior Data Analyst | Senior Data Analyst | Senior Data Analyst – Healthcare |
| Location | Austin, TX | Austin, Texas (+2 locations) | Austin, TX |
| Extensions | Full-time | Full-time, salary information | Full-time |
| Document ID hint | abc123 | abc123 | 9f771 |
Normalized values: employer acme health (A and B) and brightpath staffing (C); title senior data analyst (A and B after expanding “Sr.”) and senior data analyst healthcare (C); city austin for all three.
Signals and decisions:
- A ↔ B: Matching document ID hint (Layer 1) plus a composite-key match after title expansion (Layer 3). Merge.
- A ↔ C: Different employer string. Title similarity is high, and the description mentions Acme Health as a client (Layer 4). Send to review, or link as a “possibly same vacancy” relation instead of merging. Agency postings may represent a separate requisition.
Stored canonical record: employer “Acme Health”, city Austin, employment type full-time, salary information from Record B when available, earliest first_seen, and all source URLs retained. Record C remains a related candidate until reviewed.
Refresh Scheduling Based on Job Volatility
Not every listing needs the same attention. New listings change most often through edits, salary additions, or quick closures. Older listings are either evergreen requisitions or stale. Spend your request budget where change is likely.
| Listing Category | Suggested Refresh | Reason |
| Newly discovered (first 7 days) | Daily | Recent postings change and fill quickly |
| Active, steady | Re-query every few days | Confirms continued visibility at lower cost |
| Older (30+ days) | Lower frequency | Separates evergreen roles from stale ones |
| Possibly stale | Targeted verification | Avoids removing live jobs before confirmation |
These intervals are starting points. Tune them against your own data: measure how often listings in each category actually change or disappear, and how much each refresh costs. The date_range parameter (d for the past 24 hours, w for the past week) helps here. A daily pass with date_range: “d” focuses on recent listings, while a weekly pass without it can help re-confirm older ones.
Handle Expired and Removed Jobs
Use explicit states:
discovered → active → possibly_stale → verified_unavailable → archived
A listing can return to active when it reappears.
discovered ──► active ◄──────────────┐
│ │
│ not seen in N │
│ runs │
▼ │
possibly_stale ─────────┘
│
│ 404/410, “no longer accepting,”
│ or feed removal
▼
verified_unavailable
│
▼
archived
The key rule: “not returned in a search result” is not the same as “confirmed removed.” Search results shift with other jobs competing for those ten slots. A job can drop out of one query and still be open. Move a listing to possibly_stale only after it is missing from several consecutive runs across all queries that previously found it.
Move it to verified_unavailable only on stronger evidence: a 404/410 response, a “no longer accepting applications” notice, or removal from an authorized feed. Google’s own job-posting guidelines describe how to handle closed jobs through validThrough or removal. When you can fetch a source page legitimately, a past validThrough date is a useful signal.
Structuring Listings for Search
Define a normalized job schema.
| Field | From API or Derived | Notes |
| job_id | Internal | UUID, never reused |
| dedup_group_id | Derived | Shared by merged duplicates |
| source_doc_id | share_link | Undocumented hint; nullable |
| source_url | API | Store each source URL |
| source_attribution | API | One row per source, including source type |
| employer_name, job_title | API (company_name, title) | HTML-unescape; keep the original |
| job_title_normalized | Derived | For matching and facets |
| summary | Available snippet, where returned | Check display rights |
| city, region, country | Derived from location | Geocode where needed |
| work_mode | Derived | Remote/hybrid/on-site, only when supported by the data |
| employment_type | extensions, when available | Nullable |
| salary_raw | extensions, when available | Nullable; keep the raw string |
| salary_min, salary_max, currency, period | Parsed when supported | Don’t invent missing values |
| posted_relative | API | Relative value, such as “3 days ago” |
| date_posted_estimate | Derived | Estimate with its observation time |
| first_seen, last_seen, last_verified | Derived | Your timestamps, not the source’s |
| status | Derived | Use the lifecycle states above |
Represent missing values as NULL, never as empty strings or guesses. A filter for “salary listed” must distinguish a missing salary from a salary of zero.
Choose the Storage and Search Architecture
A relational database such as PostgreSQL is a practical system of record. It gives you constraints, transactions, and INSERT … ON CONFLICT upserts, and with extensions it can handle geographic queries at moderate scale.
A dedicated search engine (Elasticsearch or OpenSearch) is better at relevance-ranked full-text search, geo-distance filters, and typo tolerance across large indexes, but it isn’t designed to be your only copy of the truth. Many platforms use a relational database for canonical state and history, while an indexing worker pushes changes to the search engine.
The cost is keeping the two consistent. An updated_at watermark or an outbox pattern helps. Choose based on your query patterns and team. No option is always best.
Design a Reliable Upsert
For each normalized record:
- Match it against existing records using the layers above.
- Upsert the canonical row, updating changed fields and filling nulls without overwriting known values.
- Insert an observation row (query, run, timestamp) so history is preserved.
- Set last_seen.
- Record the source URL in the provenance table.
- Mark the record for re-indexing.
Wrap the database changes in one transaction per query so a crash leaves either all of a query’s results or none. Because the raw response is already stored and keyed by run, a failed query can be reprocessed without calling the API again.
Scaling the Aggregation Pipeline
As volume grows, the bottleneck becomes orchestration. Replace the single loop with a queue (a database table, Redis, SQS, or similar) and a small pool of workers that partition runs by region and priority, checkpoint progress per query, and route exhausted retries to a dead-letter queue. Batch database writes and index asynchronously so a slow search cluster never blocks collection.
Illustrative workload calculation (hypothetical platform): 150 role variants × 40 metro areas = 6,000 queries, or 6,000 requests per day. At a 60 requests-per-minute limit, pacing alone takes about 100 minutes of wall-clock time. Add targeted re-checks of possibly stale listings, and the plan’s rate limit, not your code, sets the ceiling. That’s the point at which to evaluate higher limits.
Actual cost depends on the provider’s current pricing and how many credits each request uses, so model it from the published rates rather than from estimates.
Production Metrics to Monitor
- Collection success rate and failed requests, by error class (429, 5xx, 200-with-error)
- Query completion time per run and per partition
- Records collected, new records, and the share of results that were duplicates
- Records updated and listings verified unavailable
- Indexing lag (database write to search-index availability)
- API usage and spend against budget
- Data freshness (median age by region)
- Empty-result rate per query (inventory health)
Set alert thresholds from your own baseline after a few weeks of runs.
API-Based Aggregation vs. Direct Job Board Scraping
| Factor | SERP API | Direct Scraping of Job Boards |
| Implementation complexity | One integration, one schema | One extractor per source |
| Maintenance | Provider handles result parsing | Fix every layout change |
| Source coverage | Whatever the search engine returns for your queries | Exactly the sources you target, if accessible |
| Structured data | Consistent fields; some details depend on the source | Varies by source; often depends on the page |
| Freshness | As fresh as the search engine | As fresh as your crawl schedule |
| Operational scalability | Bounded by plan and rate limits | Bounded by proxies, blocks, and engineering capacity |
| Access restrictions | Handled at the search-results layer | Responsibility per site |
| Data rights | Still need review for republishing | Requires review per source |
| Cost predictability | Per-request pricing | Infrastructure plus engineering time |
A search-results job listing scraping alternative reduces extraction work. It doesn’t remove the need for authorized feeds and partners, and it doesn’t settle data rights. Whether you may store, display, or republish a listing depends on applicable terms and the rights attached to the content, so involve legal review before republishing descriptions at scale.
A practical approach combines feeds for inventory you’re licensed to show, search results for discovery and visibility signals, and direct extraction only where access is permitted.
Where SERPHouse Fits
SERPHouse’s role is the discovery stage. The Google Jobs API returns Google job results for a query, location, and language as structured JSON, including titles, employer names, location, description snippets, extensions, and apply options, with documented request parameters and status codes.
Scheduling, normalization, deduplication, lifecycle management, and search are your platform’s responsibilities. That’s true of any search-data provider.
For larger workloads, SERPHouse offers asynchronous batches with postback and pingback delivery for supported result types. If your job-collection volume exceeds the standard rate limit, or you need batch delivery for job queries, contact the team to discuss limits and options.
Conclusion
A scalable job aggregation platform needs clear ownership at each stage. A search-results API can handle discovery across many sites through one integration. The parts that determine product quality, query design, deduplication, a lifecycle that distinguishes “unseen” from “closed,” and a consistent index, are yours to build.
For search data for the collection layer, start with the SERPHouse Google Jobs API and test it against your own query inventory. For higher-volume requirements, contact SERPHouse to discuss custom plans.